Durable state
A state cell is a named value a run reads and writes directly:
(scope, key) -> value, a small JSON document. It survives replay and
the run, and it’s the same cell from a shell step, a polyglot script, an
SDK, or a graph’s state step.
Concepts covers what a cell is and when to use one. This page is how, including the operations that stay correct when two runs touch the same key at once.
Where cells fit
Section titled “Where cells fit”| You want | Reach for |
|---|---|
| A value between steps of one run | Run-scoped cell, or spool output set |
| Not re-running an expensive command on replay | spool step, whose result is a checkpoint |
| A value from this run’s last execution | Entity-scoped cell |
| “Has anyone handled this id?” | add on an entity cell |
| A shared counter or quota | incr on an entity cell |
| Only one run at a time in a region of the pipeline | a concurrency: lease |
add answers “not more than once, ever”: the claim outlives the run,
so a second run finds the key taken and skips. A lease answers “not at
the same time”: it is held until the run ends, whatever the outcome, and
the next run in line proceeds. The group can be per key:
concurrency: "record-{{ input.record_id }}" on a step gives one lease
per record, and a run waiting for one holds no agent. See run
admission for a whole run’s
concurrency:, and
job-level concurrency:
for one job’s.
Scopes
Section titled “Scopes”Every cell lives in one of two scopes:
| Scope | How you address it | Lifetime |
|---|---|---|
| Run | the default - no flag | Dropped when the run is collected |
| Entity | --entity <name> (entity: on a graph step) |
Outlives every run |
Run scope is a durable scratchpad for one run. Entity scope is cross-run
memory: two runs in the same project that pass the same entity name
reach the same cell. You choose the name (crawler, ledger,
counters), and it’s unique within the project.
Keys starting _spool/ are Hyperspool’s own. You can read them; writing
one is refused, on the canvas as you type it and again when the step
runs.
spool state set cursor 1200 --entity crawler # writespool state get cursor --entity crawler # 1200spool state list --entity crawler # key<TAB>value<TAB>version per linespool state delete cursor --entity crawlerOn a graph the same verbs are op: get|set|delete on a state step.
The SDKs have get, set, delete, list and add, spelled the way each
language spells things: state_get(key, entity=...) in Python. incr
and cas are on the CLI and graph steps only. Script
commands lists every subcommand with
its output and exit codes.
The poll cursor
Section titled “The poll cursor”The main use of entity scope. Run this on a schedule and each tick picks up where the last one left off:
since="$(spool state get last-seen --entity digest)"latest="$(spool step poll -- sh -c 'echo $(( $1 + 10 ))' _ "${since:-0}")"spool step notify -- echo "items ${since:-0} to $latest"spool state set last-seen "$latest" --entity digestThree consecutive runs print items 0 to 10, items 10 to 20 and
items 20 to 30. The ${since:-0} covers the first tick: spool state get exits 0 and prints nothing for a cell nobody has written, so
$since is an empty string rather than an error.
A step’s checkpoint can’t do this: checkpoints belong to one run, and this value has to cross from one run to the next.
When two runs want the same key
Section titled “When two runs want the same key”get then set has a gap in the middle. Two runs read the same absent
cell, both see nothing, both decide they’re first, and the record gets
processed twice. Three operations close that gap.
All three want entity scope. Only one run can reach a run-scoped cell,
so a claim on it never loses and a swap has nobody to race: the step
looks like a dedup while deduping nothing, and that only surfaces the
day two runs arrive together. A state step with op: add or op: cas
and no entity: is refused when you save the graph. In a script,
spool state add and spool state cas without --entity are allowed,
and act on a cell only this run can see.
add - claim a key
Section titled “add - claim a key”Writes the cell only if nothing holds it yet, and tells you whether you won. In a shell that’s the exit code: 0 you won, 3 someone else holds it, anything else means something broke.
order_id=1042rc=0spool state add "seen-$order_id" --entity ledger || rc=$?case $rc in 0) spool step process -- echo "processing order $order_id" ;; 3) echo "order $order_id already handled" ;; *) exit 1 ;; # unreachable agent, refused write - not an answeresacBranch three ways. A plain if spool state add … sends every failure
down the else branch, so an agent that couldn’t reach the server reads
as “someone else has it” and the record is silently skipped. Reserve the
skip for exit 3.
Keep the || rc=$?. Scripts run under bash -eu, so a bare
spool state add followed by case $? never reaches the case: losing
the claim exits 3, errexit ends the run there, and the second run of a
dedup ledger fails with no output at all.
That’s a dedup ledger, and it makes a workflow safe to trigger twice
with the same payload. The value is optional (it defaults to true),
since usually only the answer matters, though you can store something
useful:
spool state add "seen-$order_id" "$(date -Iseconds)" --entity ledgerA ledger is for duplicates the run discovers about its own work. If what
repeats is the submission, such as a webhook that delivers twice, the
caller already knows, and spool submit --idempotency-key <k> is
cheaper: the second delivery is answered with the first run, and no
second run is created, admitted, or counted.
On a graph this is a state step with op: add, whose output is
{"claimed": true|false}. Gate the work on it:
{ "version": "hyperspool-graph/v1", "nodes": [ { "id": "claim", "type": "state", "config": { "op": "add", "key": { "$template": "seen-{{ input.order_id }}" }, "value": true, "entity": "ledger" } }, { "id": "process", "type": "shell", "if": "nodes.claim.output.claimed", "config": { "run": { "$template": "./process-order.sh {{ input.order_id }}" } } } ], "edges": [{ "from": "claim", "to": "process" }]}A duplicate trigger still starts a run. The run does nothing, and leaves a record that it happened.
incr - count without losing updates
Section titled “incr - count without losing updates”{ "id": "bump", "type": "state", "config": { "op": "incr", "key": "processed", "by": 1, "entity": "counters" } }From a script, same op:
n=$(spool state incr processed --entity counters --op tick)The step’s output is {"value": <new total>, "version": <n>}, and the
CLI prints the new value. by: defaults to 1 and may be negative, so a
quota that hands out credits and returns them is two steps with
by: -1 and by: 1.
Concurrent runs each land their own increment instead of overwriting one another. A cell holding something other than a number fails the step rather than resetting your count.
cas - a read-modify-write of your own shape
Section titled “cas - a read-modify-write of your own shape”For updates that aren’t addition. get returns the cell’s version
alongside its value; cas writes only if the version hasn’t moved:
{ "id": "read", "type": "state", "config": { "op": "get", "key": "config", "entity": "settings" } },{ "id": "merge", "type": "code", "config": { "script": "…produce the new document…" } },{ "id": "write", "type": "state", "config": { "op": "cas", "key": "config", "expected": { "$expr": "nodes.read.output.version" }, "value": { "$expr": "nodes.merge.output.document" }, "entity": "settings" } }The get carries the same entity: as the cas; otherwise the version
you read belongs to a different cell than the one you write.
From a script the exit code carries the answer:
v=$(spool state version config --entity settings)doc=$(spool state get config --entity settings)doc=$(python3 -c 'import json, sys; d = json.loads(sys.argv[1]); d["theme"] = "dark"; print(json.dumps(d))' "$doc")rc=0spool state cas config "$doc" --expect "$v" --entity settings --op merge || rc=$?case $rc in 0) echo "landed" ;; 3) echo "someone else wrote first" ;; *) exit 1 ;; # unreachable agent, refused write - not an answeresacThe CLI prints nothing; exit 3 means someone wrote between your read and
your write, so retry or fail the run. On a graph the step’s output is
{"swapped": true|false}.
Read the version before the value. With version first, a write landing between the two calls leaves you an old version and a new value, so the swap fails and you retry. With value first, you hold a stale value and a version that already moved, so the swap succeeds and overwrites the other run’s write. That failure is silent and shows up only under contention.
Omitting expected: on a graph means “only if the cell is absent”,
which is what add does. The CLI has no spelling for that; use spool state add.
State and replay
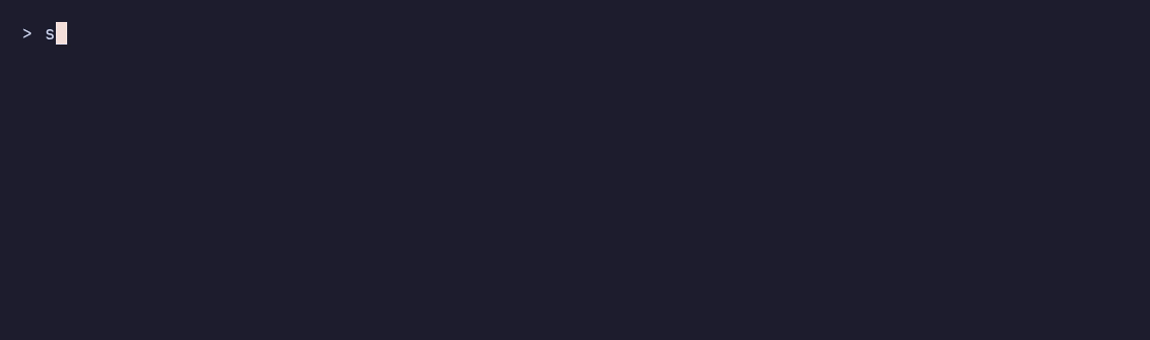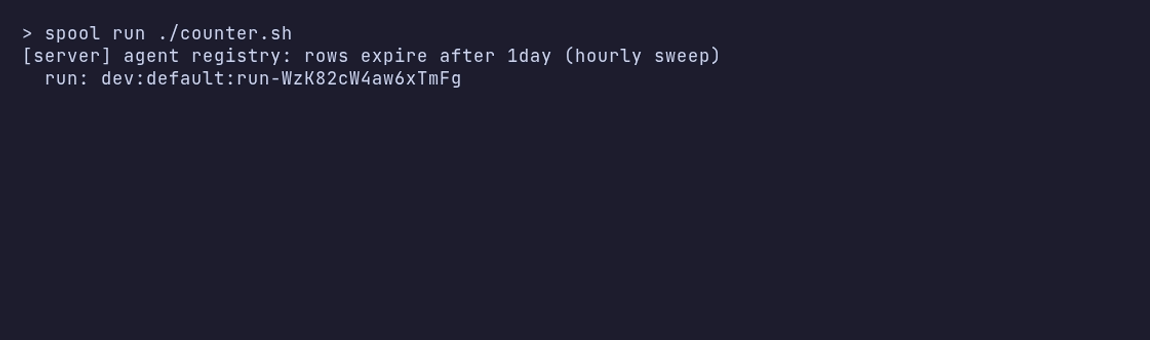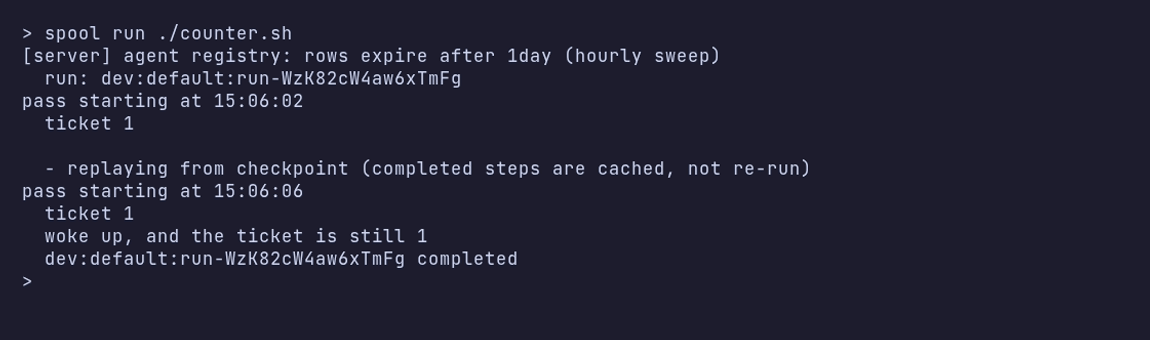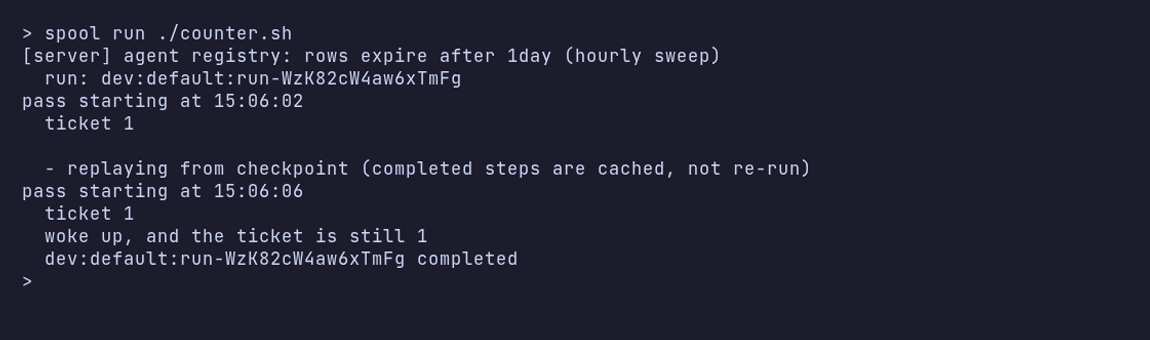
Section titled “State and replay”A state read or write is a plain operation. A polyglot script runs
again from the top on every wake, so get, set and delete run again
on each pass and get sees whatever the cell holds now, including other
runs’ writes. Prefer last-write-wins or idempotent values, and don’t put
a state call inside spool step: a step body can’t call spool.
add, cas and incr are recorded, on the CLI and on a graph. A
replay pass reads back the first answer instead of racing again, so a
run never loses a claim to its own earlier attempt, swaps twice or
counts twice. A lost swap is recorded too, because the run acted on it.
incr and cas record their answer under --op <name>, which
defaults to the key. A loop that swaps one cell several times needs a
distinct name per attempt, and reusing a name in one run is refused.
A retry: re-runs the job on purpose, recorded answers and all, so a
retried job’s incr counts again, and its cas re-attempts with a
version its own first attempt already moved, reporting “someone else
got there first” on a swap that in fact won. add survives a retry,
because the cell records who claimed it. If a job carries retry: and
counts, add a marker first or make the whole job idempotent.
Reading a cell from outside the run
Section titled “Reading a cell from outside the run”The server holds the cells, so reading one needs neither a live run nor a free agent.
In the console, the run page has a State section listing the run’s
cells and their current values. Hyperspool’s own _spool/ cells (a
graph’s recorded step outputs, for instance) sit under a separate
disclosure below yours.
From a terminal, name the scope, since out here you are not inside a run:
spool state get progress --run dev:default:run-jD3sGl # that run's own cellsspool state list --run dev:default:run-jD3sGl # all of themspool state get last-seen --entity digest # the project's storeA bare run-jD3sGl works too; it is qualified with your active project.
The output matches what the same command prints inside a job, and an
unset cell prints nothing and exits 0.
Over HTTP the same two scopes are
GET …/runs/{id}/state[/{key}] and GET …/entities/{entity}/state[/{key}].
Fetching one key also returns its version, which a poller compares to
notice a change without re-reading the value.
This is how a run publishes something for a reader outside it: the run writes the cell and the reader fetches it. A reader can only get answers the workflow prepared.
Before you rely on it:
- Reading a run’s own cells needs
Viewer; entity scope needsMember. A run’s cells are its working data, like its logs. The entity store spans the project and outlives every run, so it sits at the level that could already read it by running a workflow that does. - Cells are not masked. Secret masking applies to logs and not here, because a workflow reads a cell back as the real value. A cell holding a credential hands back that credential, so write accordingly.
- Nothing outside a run can write. A write from outside would race the workflow that owns the cell. To tell a running workflow something, send it a signal.
Run-scoped cells last as long as the run’s logs, so reading a swept run gives back nothing: an empty listing, or a 404 on a named key.
Cleaning up
Section titled “Cleaning up”Cells in run scope go when the run is collected. Entity cells stay until a run removes them, with this in a job or script:
spool state delete last-seen --entity digestFrom a terminal the command is refused, since only a run writes cells. To clear one by hand, submit a one-line script that runs it.
Deleting a project removes every cell under it, both scopes.
Advanced
Section titled “Advanced”Appending to a list from several runs
Section titled “Appending to a list from several runs”A list that several runs append to at once needs a read, a change and a
swap, retried when the swap loses. To keep it correct across a spool sleep, try add first, then fall back to cas with one --op name
per attempt:
item="$(spool step pick -- sh -c 'echo "job-$$"')"
rc=0spool state add items "[\"$item\"]" --entity inbox || rc=$?attempt=0while [ "$rc" = 3 ]; do  attempt=$((attempt + 1))  v="$(spool state version items --entity inbox)"  list="$(spool state get items --entity inbox)"  new="$(python3 -c 'import json, sys; print(json.dumps(json.loads(sys.argv[1]) + [sys.argv[2]]))' "$list" "$item")"  rc=0  spool state cas items "$new" --expect "$v" --entity inbox --op "append-$attempt" || rc=$?done[ "$rc" = 0 ] || exit 1
spool sleep 2secho "appended $item after $attempt swaps"
Six of those submitted together leave six items in the list. Both
answers are recorded, so the pass after the sleep takes the same path
and reads them back. Choosing between add and cas from a live get
would take a different path on replay and fail the run.
An append is at least once: an agent that dies after the write and
before its answer is recorded comes back, loses the swap it had in fact
won, and appends again. The same gap applies to incr on an existing
cell, where the next pass counts again. The window is small; if a count
has to be exact across a crash, add a per-run marker first and
increment only when the claim is yours. add itself is safe, because
the cell remembers who claimed it.
Debouncing: act on the last of a burst
Section titled “Debouncing: act on the last of a burst”“Stamp a marker, sleep, then check whether I’m still the newest” doesn’t
work in a script. The stamp is a set, so the replay pass after the
sleep stamps it again and every arrival concludes it was last.
Draw a ticket instead. incr is recorded, so the number a run drew
before the sleep is the number it still holds after:
key=order-7value="$(spool step value -- date +%H:%M:%S.%N)"mine=$(spool state incr "ticket:$key" --entity debounce --op ticket)spool state set "latest:$key" "$value" --entity debounce
spool sleep 3s
# A live read, so it sees later arrivals' tickets.if [ "$mine" = "$(spool state get "ticket:$key" --entity debounce)" ]; then  echo "handling $(spool state get "latest:$key" --entity debounce)"fi
Five arrivals half a second apart print one handling line, with the
last one’s value. On a graph the same shape uses cas on the version
the stamp returned, since a graph step runs once per run and needs no
ticket.
The latest: cell is a plain set, so a waking loser stamps it again
with its own older value on the way past. That is harmless when the
winner wakes last, the normal case, and it is why the ticket decides who
acts. If the value has to be the last arrival’s, carry it in the ticket
cell itself with a cas.
On a graph, a get reads back your own write
Section titled “On a graph, a get reads back your own write”A graph records a cell write, so a get of a cell this run has
already written answers from that record without going to the store.
That keeps a read the same across replay passes, but a graph can’t
write a cell, wait, and then read it to see what another run did in the
meantime: it sees its own value. Settle that with cas on the version
the write returned, which does go to the store.
A polyglot script is the other way round: spool state get reads the
store every time it runs, so it sees other runs’ writes. That is why
anything derived from it has to be pinned by a recorded op (add,
cas, incr) before the script branches on it.