Repeating work
There is no loop keyword. Which shape of repetition you want depends
on whether you know the list up front, whether the iterations are
independent, and how long the whole thing runs.
| You know | You want | Reach for |
|---|---|---|
| The combinations, as you write | One job per combination | matrix: |
| The list, at run time | All of it, in parallel | fan_out |
| The whole shape, at run time | Work you couldn’t name up front | A computed graph |
| Only a stopping condition | One pass, then decide, nesting at most 20 deep | A graph that calls itself |
| Neither - it’s a conversation | A turn at a time | A script while loop |
| Nothing; just “again later” | A fresh run on a cadence | A schedule |
Combinations you know while writing: matrix:
Section titled “Combinations you know while writing: matrix:”In a pipeline, when the axes are fixed as you write, declare them and
the job runs once per combination. exclude: carves combinations out of
the full grid:
test: matrix: values: db: [postgres, sqlite, mysql] shard: ["1", "2"] exclude: - { db: sqlite, shard: "2" } - { db: mysql } steps: - name: test run: ./run-tests.sh --db ${{ matrix.db }} --shard ${{ matrix.shard }}Six combinations become three. An exclude: entry is a partial
combination: the dimensions it names must all match, and the ones it
omits are wildcards, so { db: mysql } drops the whole mysql row. Values
match as written, so a quoted "2" in values: stays quoted in
exclude:. A misspelled dimension or value, an empty entry, or an
exclude list that removes every combination fails the compile instead of
quietly running the whole grid.
It stays one job, so depends_on: [test] is one edge that waits for all
of them. See matrix:
for max_parallel:, fail_fast:, rate: and how retry: applies per
combination.
The axes have to be literal lists. A ${{ … }} hole in matrix.values
is refused, because a run’s job set is fixed when it starts. For axes
known only at run time, use fan_out if you have a list, or a computed
graph if you don’t yet have a shape.
A list you have in hand: fan_out
Section titled “A list you have in hand: fan_out”The list arrives from an upstream step and every item is independent:
build ten targets, notify twelve people, resize a directory of images.
fan_out runs the same body once per item:
- id: build type: fan_out config: items: { $expr: nodes.targets.output.list } max_parallel: 4 body: type: shell config: run: { $template: "make {{ item }}" }The body sees each element as item and its position as index. The
step’s output is the array of body outputs in item order, whatever order
they finished in.
A hundred items is the ceiling, for
fan_outandmatrix:alike. A literal list over that is refused byspool workflow checkand on save; a computeditemsfails the step when it resolves. Aworkflowbody doesn’t lift it, since it’s one effect per item either way. Past a hundred, fan out over batches, or drive the list from a script loop:spool activity submithas no such cap.
max_parallel caps how many run at once. on_error decides what a
failing item does to the rest: halt (the default) fails the step once
the in-flight window settles; continue leaves failed items as null
slots and lets the step succeed. The run-scoped state cell
_spool/graph-fan-out-items records why each slot is null: per fan-out,
each item’s index, status and error. Read it with
spool state get _spool/graph-fan-out-items --run <id>.
Pacing: rate
Section titled “Pacing: rate”max_parallel bounds how many items are in flight. A service that
answers 429 counts requests per minute, and four in flight is still
hundreds an hour when each takes a second. rate bounds that:
- id: judge type: fan_out config: items: { $expr: nodes.rows.output.list } rate: { limit: 20, period: 1m } max_parallel: 4 body: type: http config: { url: "https://api.example.com/score" }The first twenty items go out, four at a time. Once that window has
settled the step waits one full period, then sends the next twenty. A
max_parallel larger than limit does nothing, since a window only
holds limit items.
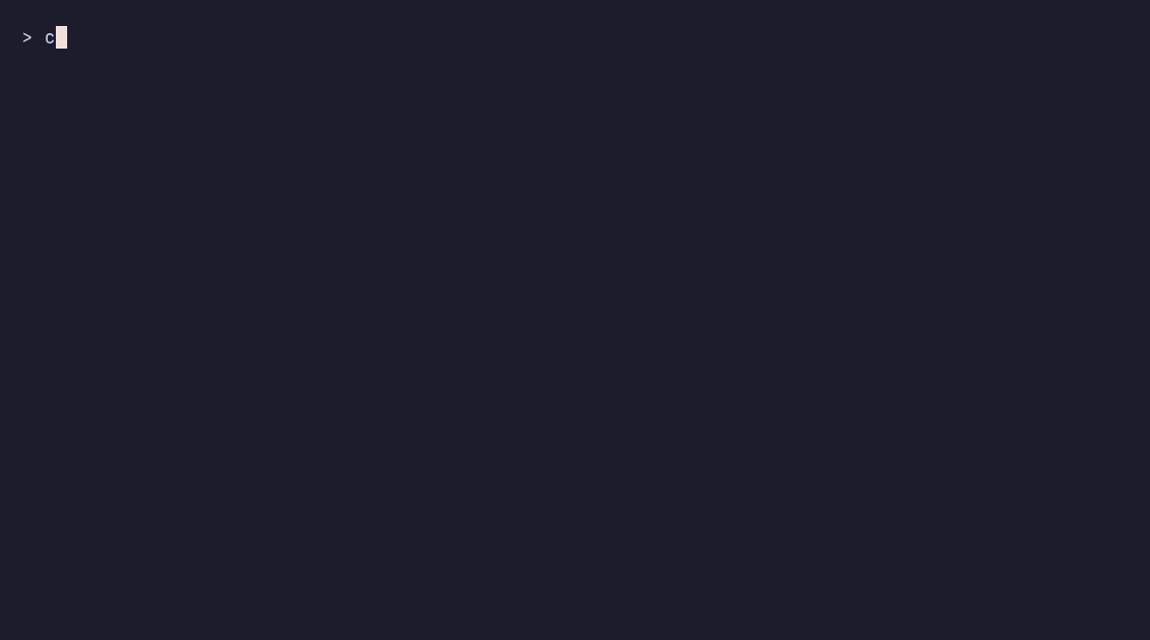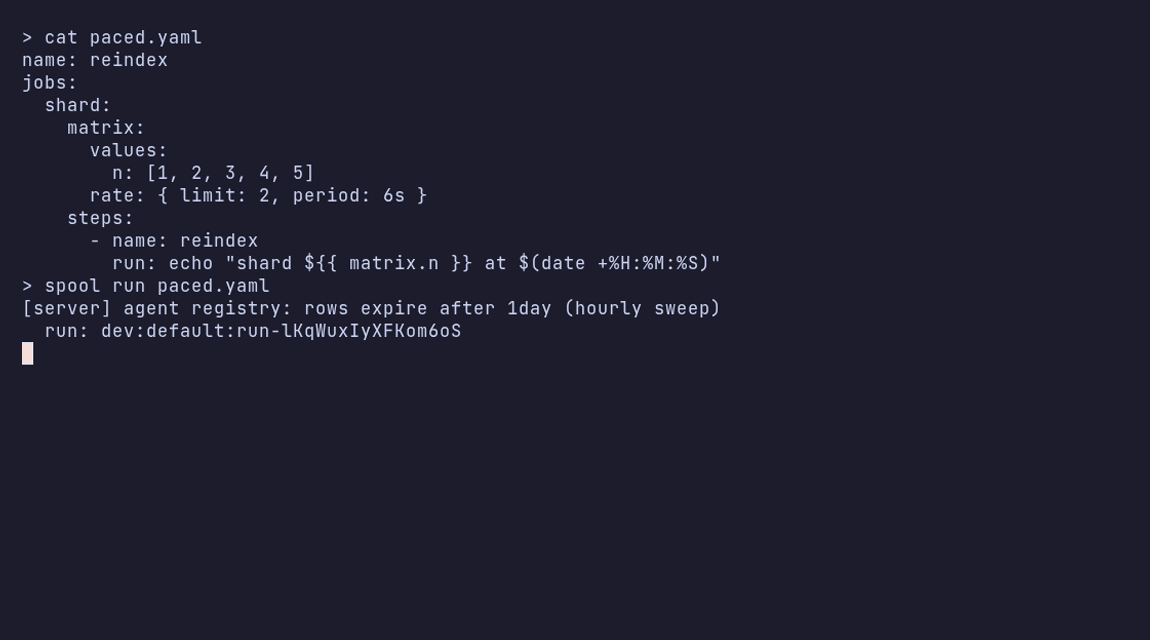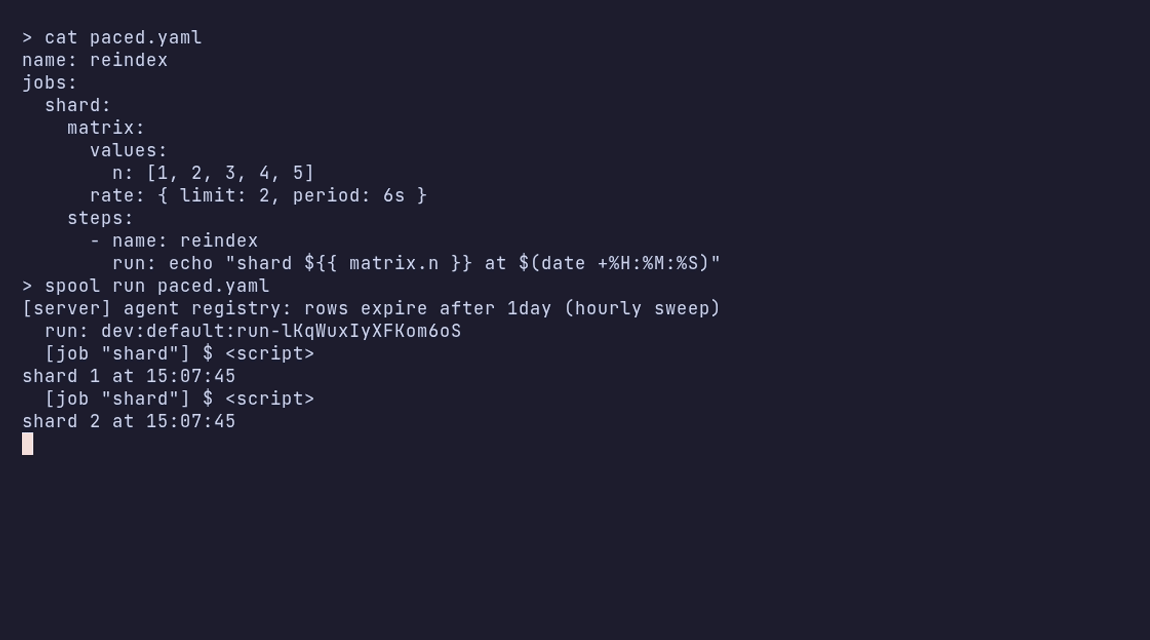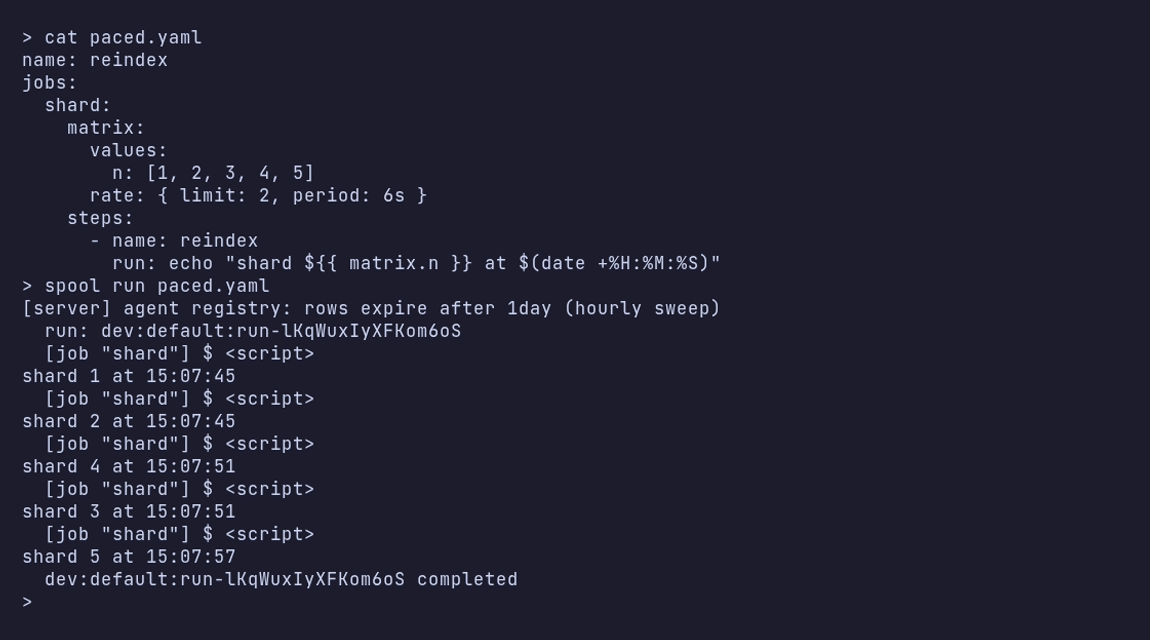
In a pipeline the same knob sits on matrix: as rate:. Here a
five-shard matrix runs at two per six seconds, as the timestamps the
shards print show:
The last window gets no wait after it, so a list no longer than limit
never waits at all.
The wait between windows is a durable timer: the run is asleep and holds no agent, and a restart mid-wait resumes where it was instead of sending a window again. Eighty items at twenty a minute cost three one-minute waits on top of the time the windows take.
The budget is per step, per run: two runs fanning out to the same API
each get their own twenty. When the ceiling has to hold across runs, use
a top-level throttle: on the
pipeline or graph, which counts run starts across the project. Pacing
doesn’t raise the hundred-item ceiling either.
One activity per item, or one run per item
Section titled “One activity per item, or one run per item”The body is either an activity kind (http, shell, code) or
workflow, depending on what one item’s work is. An activity body is
one cheap call per item, and everything lands in this run’s history. A
workflow body starts a child run per item:
- id: release type: fan_out config: items: { $expr: nodes.plan.output.services } max_parallel: 4 body: type: workflow config: graph: { name: service-release } input: { service: { $expr: item } }Use it when one item’s work is more than one step, or when you want each item inspectable on its own: a child has its own page, history and rerun-from-step (see One child per item). The output is still the list of per-item results, in item order.
The per-item fields (retry, requires, agent, timeout) describe
how one activity runs, so a workflow body refuses them; set
them inside the child, on the step that needs them.
A body that waits (wait, approval) is refused either way. One item’s
approval is the same question as the next one’s; put the gate in the
graph the workflow body names.
A shape you compute: a generated graph
Section titled “A shape you compute: a generated graph”fan_out repeats one body over a list. When the work isn’t uniform
(this target needs a build and a sign, that one only a build, a third
waits for an approval) there is no single body to repeat. Build only what
changed does this for a monorepo. Compute the
graph instead: one step emits a graph document, and a workflow step
runs it.
- id: build_all type: workflow config: definition: { $expr: nodes.generate.output.graph }The child is a real run with its own history and retries, validated when it starts. The cost is coarse sequencing, since the parent waits for the whole child. Composition shows a complete one, including the step that generates the document.
A stopping condition: a graph that calls itself
Section titled “A stopping condition: a graph that calls itself”When you can’t compute the list up front (poll until the export is
ready, page through an API until the cursor comes back empty, retry a
flaky system with your own backoff), do one pass, decide, and call
yourself again. A workflow node can name any stored graph in the
project, including the one it’s in.
Each pass is a child run of the one before, and children nest at most 20 levels deep. The pass that would go deeper fails, and every pass above it fails with it. For a loop that may need more passes, use a script loop or a schedule.
A loop that pages through an API looks like this:
version: hyperspool-graph/v1nodes: - id: page type: http config: url: { $template: "https://api.example.com/orders?cursor={{ input.cursor }}" } - id: more type: switch config: cases: - name: again when: "input.attempt < 20 && nodes.page.output.body.next_cursor != ''" default: done - id: next type: workflow if: "nodes.more.output.branch == 'again'" config: graph: { name: sync-orders } input: cursor: { $expr: nodes.page.output.body.next_cursor } attempt: { $expr: input.attempt + 1 }edges: - { from: page, to: more } - { from: more, to: next }Publish it as sync-orders and start it with
{"cursor": "", "attempt": 0}. Each pass fetches one page and either
stops or starts the next pass as a child run with the cursor it just
received.
The switch is the terminator: its default branch ends the
recursion. An exit expression that can error (a missing key, a null)
fails the run instead of stopping it, so make the exit the default and
the continue the case. The start input carries attempt because the
first pass reads it.
Keep a bound of your own in the condition. input.attempt < 20 ends
the loop cleanly at the nesting limit, and stops it the day an API
starts returning the same cursor.
Each pass runs the published graph. A graph: reference resolves when
the child starts, to the published version unless it pins one. Save a
draft and the running loop keeps the old version; publish and the next
pass picks up the change.
Every pass is its own run, with its own log, nested under its parent in the console. The parent waits until the child finishes, and a recursion that pauses an hour between passes holds no agent while it waits.
To check the terminator without starting any children, press Try it
on the canvas. A dry run stubs the http
and workflow steps with what they returned in the last real run, runs
the switch for real, and shows which branch it took.
Only-once, across passes
Section titled “Only-once, across passes”A recursion that acts on records sees the same record twice if a pass is retried. An entity-scoped claim makes that safe; see claiming a key.
A turn at a time: a script loop
Section titled “A turn at a time: a script loop”Inside a polyglot script, a loop is a loop:
turn=1while [ "$turn" -le 20 ]; do reply="$(spool step model -- ./ask-model.sh "$goal")" [ "$reply" = "done" ] && break spool step tool -- ./run-tool.sh "$reply" turn=$((turn + 1))doneThe script re-runs from the top on every wake, and each completed
spool step returns its recorded result instead of running again, so
the loop fast-forwards to where it left off. The code between spool
calls re-executes on every pass, so keep it free of side effects.
Agent loops works this shape through end to end,
including why every turn can reuse one step name.
How long a loop can be
Section titled “How long a loop can be”Every suspend (spool sleep, wait signal, activity wait) re-runs
the script from the top, returning each recorded step from its checkpoint.
One lookup is cheap, but a loop of M iterations that suspends once per
iteration replays 0, then 1, … then M-1 iterations: total work grows
with M². A suspending loop is comfortable in the hundreds of iterations.
Past that, do more per iteration (batch a minute of samples into one
step) or use a schedule with an entity-scoped cursor,
where each tick is a fresh run with nothing to replay. A loop that never
suspends has no such limit.
Again later: a schedule
Section titled “Again later: a schedule”If “repeat” means “every night” rather than “until done”, use a schedule. It fires a fresh run per tick, and an entity-scoped state cell tells the next tick where the last one got to.
spool schedule create -w sync-orders --every 1d --input '{"cursor": "", "attempt": 0}'This is the cheapest shape, and usually the right one for anything measured in hours or days. Use recursion when the passes have to be back-to-back and carry state, and a schedule when they only have to happen again.