
Building a GitHub repo, end to end
From an empty account to a green check on a pull request. The example builds one repo for three targets - Linux x86-64, Linux arm64 and macOS arm64 - because cross-platform is where the interesting decisions are.
Both routes are here: the CLI throughout, and the web UI where it is the better tool. Neither is a subset of the other.
Roughly half a day, and most of that is machines rather than pipelines.
Before you start: the runners are yours
Section titled “Before you start: the runners are yours”There is no hosted runner pool. Work executes on agents you run, on your own machines, and an agent only claims jobs whose capabilities it advertises. Three targets means three hosts (or VMs, or containers) with your toolchain on them.
If you already run your own CI fleet this is familiar. If you have been using hosted runners, this is the real cost of the move and it is worth deciding on before the rest.
1. Sign in
Section titled “1. Sign in”spool login https://api.hyperspool.dev # paste a PAT from Settingsspool where # which server, and whyThat writes ~/.config/spool/config.toml with your org and project.
Runs, agents, secrets and credentials are all scoped to the project.
2. Stand up the agents
Section titled “2. Stand up the agents”Mint a token per machine. The capabilities you name are a ceiling the agent cannot widen at runtime:
spool agents issue linux-amd64-1 --project acme/web --expires-in 90d \ --cap shell --cap polyglot --cap linux-amd64Repeat for linux-arm64-1 and darwin-arm64-1. The architecture tags
are yours to invent - Hyperspool has no built-in notion of one, and
linux-amd64 is just a string you will match on in a moment.
On each Linux host:
curl -fsSL https://hyperspool.com/install.sh | sh -s -- \ --service --server https://api.hyperspool.dev \ --id linux-amd64-1 --token csat_… --caps shell,polyglot,linux-amd64--service writes a systemd unit, wires self-update, and runs as a
throwaway DynamicUser. A build that installs its own toolchain needs a
persistent home, so pass --user root for that one.
macOS takes longer. --service needs systemd; on darwin the script
installs the binary and prints the spool agent run command for you to
supervise yourself. You write the launchd plist, and you set
HYPERSPOOL_AGENT_UPDATE_URL yourself or the agent never self-updates.
Toolchains must be on the agent’s PATH. Jobs run in a scrubbed
environment - a small allowlist plus your pipeline’s env: - so nothing
the agent happens to have in its shell leaks in. Widen it per agent with
SPOOL_ENV_PASSTHROUGH=MYAPP_*,REGION.
spool agents ls # three agents, their capabilities, last seen3. Connect the repo
Section titled “3. Connect the repo”One command. It creates a webhook for the forge, a handler that clones each pushed commit on an agent and runs the pipeline out of that checkout, and a handler that reports the result back to the commit.
spool credential set gh-read --kind bearer --token -spool credential set github-status --kind bearer --token -spool repo add https://github.com/me/app \ --credential gh-read \ --status-credential github-statusThe Repositories panel on Connections is the same thing with a form. Either way it prints the ingest URL and a signing secret, and the page to paste them into:
| Field | Value |
|---|---|
| Payload URL | the ingest URL |
| Content type | application/json |
| Secret | the signing secret |
| Events | just the push event, to start |
The two credentials are what an agent uses: one to clone, one to
post the commit status. Skip --credential for a public repo, and skip
--status-credential if you do not want a check on the commit yet -
repo add says what you lose either way.
There is no setting that says which repo this project is for. Every push carries its own repo in the delivery, which is why the hook is named for the forge rather than the repo and why the second repo you add reuses it: no new secret, nothing to paste again.
Deliveries are signature-verified and deduped on the digest of the signed body, so a redelivered push resolves to the same event and does not start a second run. The delivery-id header is deliberately not the key: it is not covered by the signature, so dropping it would let a captured body be replayed for ever.
If you would rather not paste, Hyperspool can create the webhook
through the forge’s API. That needs a token that may manage hooks
(admin:repo_hook on GitHub), stored as a credential, and then
Register on forge on the hook’s row does it. More setup than a paste
for one repo, and less for twenty:
the two ways.
4. Write the pipeline
Section titled “4. Write the pipeline”Put it in the repo, at .spool/ci.yaml, so a commit builds the pipeline
it shipped with:
name: ci
concurrency:  group: 'ci-${{ has(input.ref) ? input.ref.replace("refs/heads/", "") : "manual" }}'  policy: cancel-running
env:  # The build handler pins the pushed commit into the document as  # `input:` before spawning this. Empty on a manual run, which builds  # the default branch.  SHA: "${{ has(input.sha) ? input.sha : '' }}"
jobs:  build:    matrix:      values:        target:          - { cap: linux-amd64,  triple: x86_64-unknown-linux-gnu }          - { cap: linux-arm64,  triple: aarch64-unknown-linux-gnu }          - { cap: darwin-arm64, triple: aarch64-apple-darwin }      fail_fast: false    requires: ["${{ matrix.target.cap }}"]    timeout: 45m    env:      TARGET: "${{ matrix.target.triple }}"    steps:      - name: checkout        run: |          set -euo pipefail          git clone https://github.com/me/app app && cd app          # $SHA when a push built it; a `spool submit --ref` sets          # CI_TRIGGER_SHA to that ref instead.          sha="${SHA:-${CI_TRIGGER_SHA:-}}"          if [ -n "$sha" ]; then            git fetch origin "$sha" && git checkout "$sha"          fi      - name: build        run: cd app && cargo build --release --target "$TARGET"
A few things in there are worth naming.
requires: reads the combination, so one job spans three platforms.
Each combination claims an agent advertising its own capability.
The commit comes from the input, and the input comes from the build
handler. A spawned pipeline is a run of its own: it never saw the
push, so there is no event to read and no CI_TRIGGER_SHA waiting in
the environment. What it has is the input: the handler wrote into the
document before spawning it, which is why the clone above reads $SHA
and falls back to the manual var. Get this wrong and the job clones an
empty string.
The same goes for filtering. A top-level if: and paths_ignore:
compile into one predicate that the server evaluates when the event
arrives, so they gate a pipeline the event delivers to and do nothing
at all in a run that was spawned. spool repo add --when is where the
path filter goes in this shape - step 5 has it.
concurrency.group is per branch, and the has() in it is not
decoration. Every run carries what started it as its input:, so a
manual spool submit renders this against {"type": "manual"} - a map
with no ref - and reading a key that is not there is an error. A group
that fails to render refuses the submit outright, so the bare
${{ input.ref }} form works on every push and rejects the run you were
testing with. The replace is only for looks: without it the group
renders ci-refs/heads/main, and that is then what a tag filter has to
say.
Interpolate the sha into env: and read $SHA in the script, rather
than splicing ${{ input.sha }} into the command. A spliced value lands
in the script text unescaped, and a branch name is attacker-controlled
on a public repo. An env: value is never re-parsed as script text.
Check it before you push:
spool check .spool/ci.yamlspool submit --repo-path .spool/ci.yaml --repo me/app --repo-credential gh-read --ref main --follow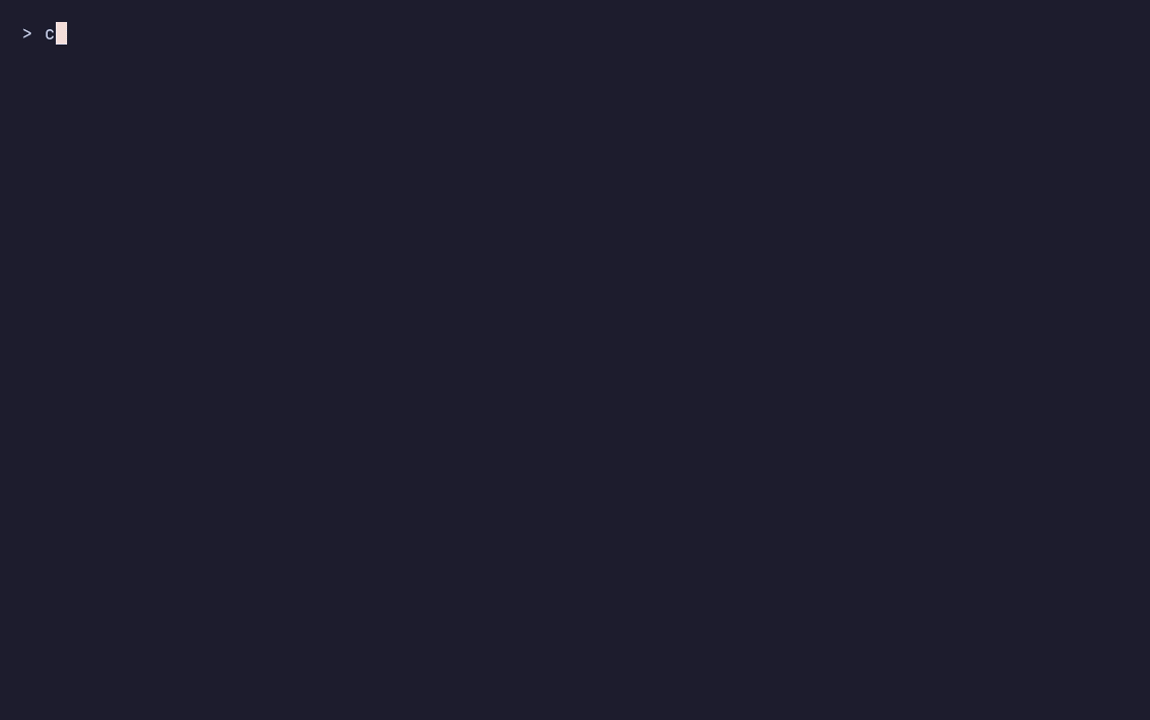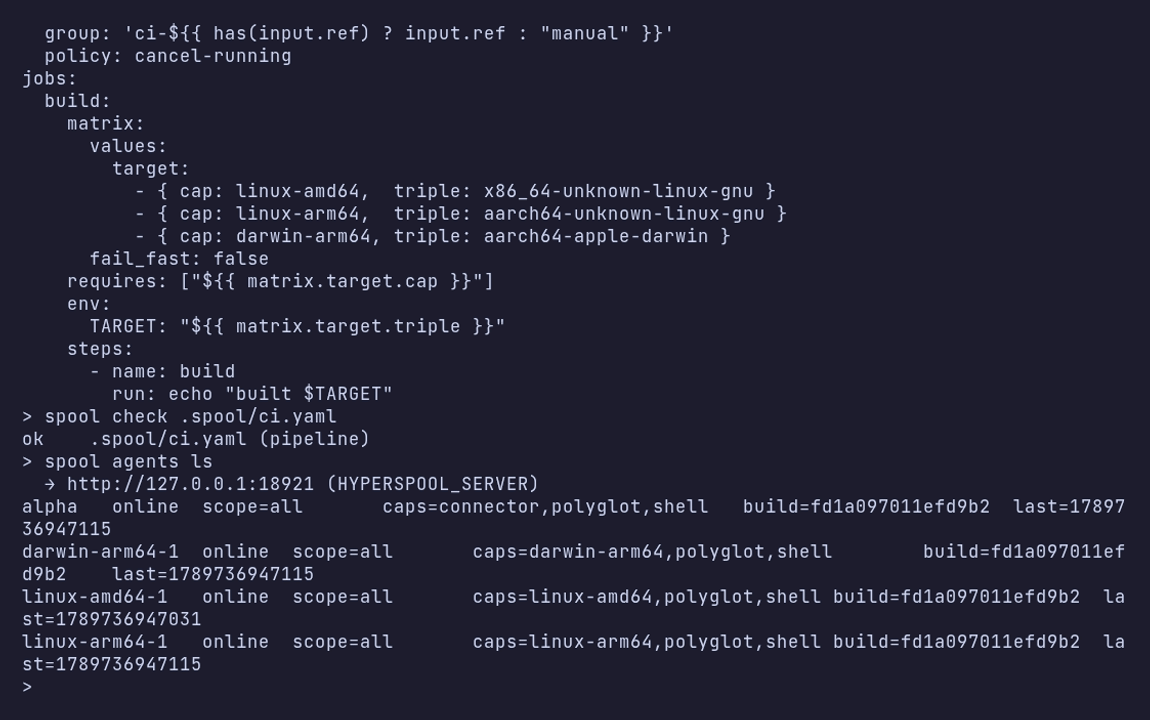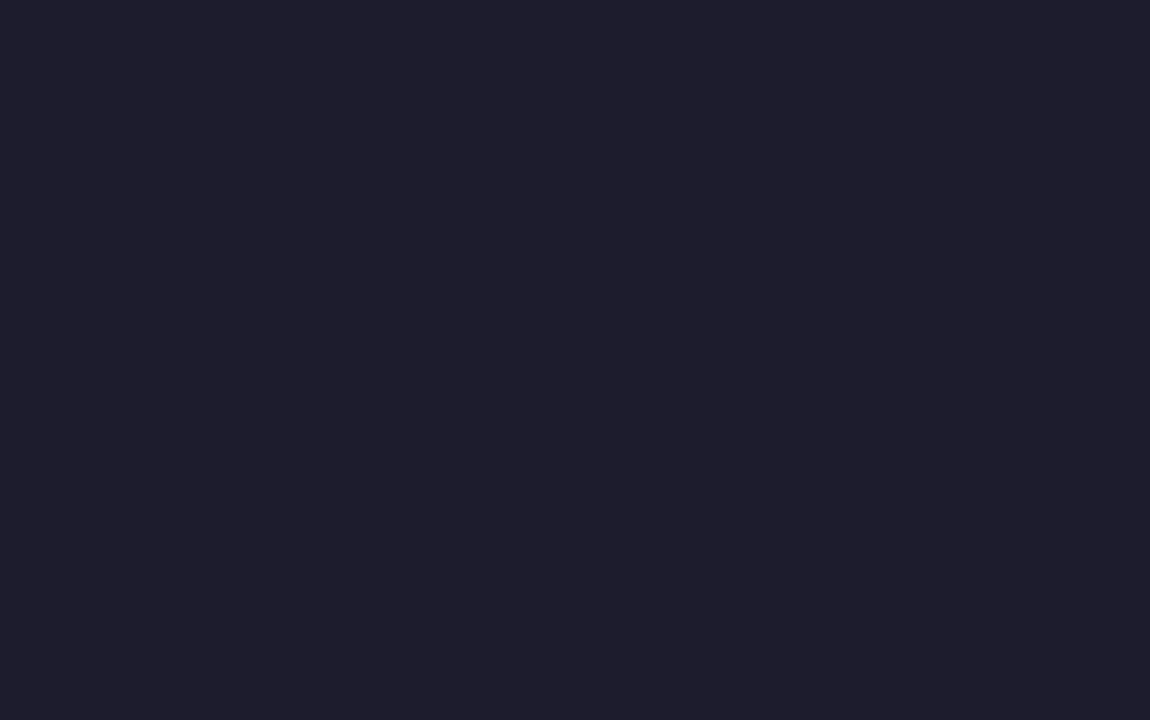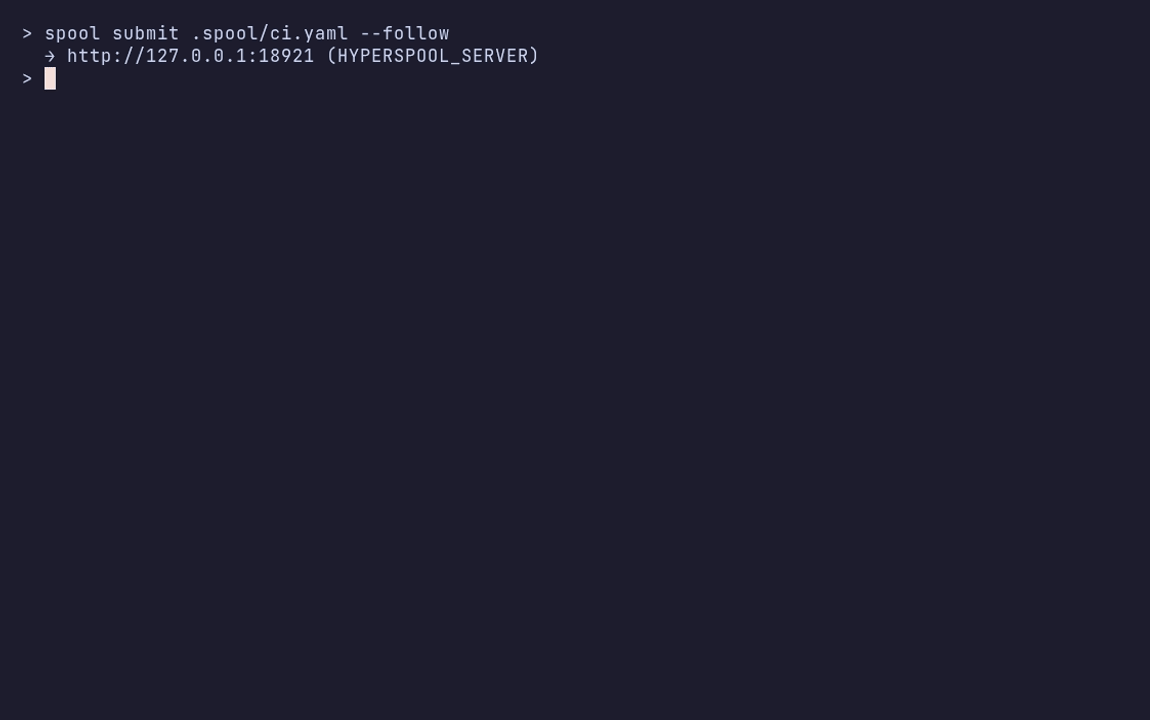
--follow opens the run’s live view. spool run .spool/ci.yaml runs it
against your working tree with no server at all, though jobs pinned to a
capability your machine does not advertise will wait rather than run.
Note where TARGET lives. A step’s env: value is a literal: the
compiler quotes it into the step script before the expression resolves,
so a hole there is refused at submit. Job-level env: renders normally,
because each value becomes its own template rather than script text.
5. Push it
Section titled “5. Push it”That is the whole setup. Commit .spool/ci.yaml, push, and the delivery
starts a run: the build handler clones your commit on an agent, reads
the pipeline out of that checkout, and runs it. The commit goes green
or red when it finishes.
Two things about why it is built that way.
The pipeline is read at the pushed commit, not from a copy stored
here. So a branch that changes its own pipeline is built by the
definition it shipped with, and editing .spool/ci.yaml takes effect on
the next push with no re-registering. The trap that avoids is
registering the file itself as the handler:
spool handler set ci .spool/ci.yaml --as yaml --on 'gh.push' # not thisThat stores a snapshot of the bytes as they were on your disk when you ran it. Nothing re-reads the file, so every push would build that copy for ever.
The clone happens on your agent, not here. For a repo connected with
spool repo add, this server sees the push envelope - repo, ref, sha,
sender, the touched paths - and the runs. The agent clones the commit
and builds it, so your code never reaches the control plane, which is
the point of running your own agents:
what that claims exactly.
Two other paths do have the server read one file. spool submit --repo-path and a workflow node’s from_repo: fetch the pipeline at
a ref through the forge API, using a credential you stored. That is the
pipeline document and nothing else - never a checkout, never your
sources - and a repo add build uses neither.
To filter what builds, give repo add a predicate. Skipping docs-only
pushes, for instance:
spool repo add https://github.com/me/app --credential gh-read \ --when '!event.paths_known || event.paths.exists(p, !p.endsWith(".md"))'It is evaluated before any run exists, so a push it declines costs
nothing, and it is ANDed with the repo’s own test - a filter cannot
widen the handler to another repo’s pushes. The paths_known guard
matters: when a forge sends no file list the set is empty, and an
unguarded exists over it would stop building rather than build
everything.
6. The check on the commit
Section titled “6. The check on the commit”--status-credential in step 3 already set this up: a handler on
run.started and the three terminal types, posting pending when the
build starts and success, failure or error when it ends. So a
commit shows a check going yellow then green rather than appearing
green out of nowhere.
Two details in it matter, because both are places to get it wrong by hand.
The four types are named rather than matched with run.*: the wildcard
also delivers run.awaiting and run.wait_expired, so a run parking
on an approval would post error on a commit that is doing exactly
what it was asked to.
It identifies the commit from the run’s tags (repo: and sha:,
stamped when the build handler spawned the pipeline) rather than from
the event. A lifecycle payload carries event.payload.trigger.* for a
run a delivery started directly, and a run an agent spawned has no
trigger fields at all - so tags are the shape that works for both. The
shipped github.report_run_status connector action does the same job
through trigger, which is why repo add does not use it.
Set HYPERSPOOL_PUBLIC_URL on the server or the check has no link back
to the run.
Then require the hyperspool context in the repo’s branch protection,
and the check gates merges.
7. Watch it
Section titled “7. Watch it”Web UI. The run page is a timeline waterfall with the pipeline strip
across the top, live output per step, and any annotations the run
attached. The runs list filters by tag, so concurrency-group:ci-main
shows one branch’s queue.
CLI.
spool runs ls --limit 10spool logs <run-id> --followspool follow <run-id> # the live TUIWhere to go next
Section titled “Where to go next”- Deploying agents - tokens, self-update, draining, and what happens when an agent dies mid-job.
- Branch routing - PRs, release branches, and deciding what runs where.
- Coming from GitHub Actions - the vocabulary table and what is deliberately absent.
- Secrets - project secrets versus connector credentials, and which reaches a job how.
And the reason to be here rather than on a CI system: the same run that builds this commit can ship it, sleep through a soak, wait for a person, and promote - one run, resuming across agent and server restarts. See the tour.