Getting started
Install the spool CLI, run a workflow, watch one survive a crash, then
run the same file on hyperspool.dev. Everything up to the last section
runs on your own machine and needs no account.
Install
Section titled “Install”curl -fsSL https://hyperspool.com/install.sh | shThat drops a single static spool binary on your PATH. Check it:
spool --versionOr download the binary yourself
Section titled “Or download the binary yourself”If you’d rather not pipe a script into your shell, download the binary directly. It’s one static file per platform:
| Platform | Download |
|---|---|
| Linux, x86-64 | https://get.hyperspool.dev/linux/spool-amd64 |
| Linux, ARM64 | https://get.hyperspool.dev/linux/spool-arm64 |
| macOS, Apple silicon | https://get.hyperspool.dev/darwin/spool-arm64 |
| macOS, Intel | https://get.hyperspool.dev/darwin/spool-amd64 |
Each one has a checksum beside it. On Linux x86-64, for example:
curl -fsSLO https://get.hyperspool.dev/linux/spool-amd64curl -fsSLO https://get.hyperspool.dev/linux/spool-amd64.sha256cut -d' ' -f1 spool-amd64.sha256 # the published checksumsha256sum spool-amd64 # must print the same (shasum -a 256 on macOS)chmod +x spool-amd64mv spool-amd64 ~/.local/bin/spool # or anywhere else on your PATHThe checksum file is signed with minisign, so you can also check that it came from us:
curl -fsSLO https://get.hyperspool.dev/linux/spool-amd64.sha256.minisigminisign -Vm spool-amd64.sha256 -P RWRLp7IQCrbka6+sosIwq3q4VtIeLvoNaIKEyX1xZeZYVIIr5NXd+etbA binary downloaded through a browser on macOS is quarantined, and macOS
refuses to run it until you clear that with
xattr -d com.apple.quarantine spool. Downloads made with curl are not
quarantined.
Run your first workflow
Section titled “Run your first workflow”A workflow can be a plain script. Write one and run it:
echo 'echo "hello from Hyperspool"' > hello.shspool run ./hello.shspool run spins up a throwaway in-memory instance, executes the file,
streams its output, and exits with the run’s status. Nothing persists:
when the command returns, the instance and its history are gone. It’s
the fastest way to try something out.
YAML pipelines run the same way:
spool run ./pipeline.yamlIn-memory or persistent
Section titled “In-memory or persistent”Durability needs a database. Without one, a run lives only as long as its process.
spool run <file>is in-memory by default - nothing survives the command.spool run --db <path> <file>persists to a sqlite file, so a one-shot run can survive a crash too.spool devkeeps state in sqlite and survives restarts. With no--dbit uses$XDG_STATE_HOME/hyperspool/dev.db;--db <path>names the file;--db :memory:makes it ephemeral.
Against a persistent instance, spool submit --follow runs a file and
opens the run’s live view, with each step checked off as it lands:
Watch a run survive a crash
Section titled “Watch a run survive a crash”A run outlives the process executing it: kill the engine mid-run and the
run picks up from its last checkpoint. spool run is in-memory, so it
can’t show that. A persistent instance can.
spool init writes a few starter workflows into the current directory:
spool initOne of them, durable.sh, is a checkpointed bash workflow. It draws a
random number, sleeps, and then does arithmetic on the number it drew:
#!/usr/bin/env bashset -e
# Drawn once, ever. From here on the number lives in the run's log.n="$(spool step "pick" -- bash -c 'echo $(( RANDOM % 100 ))')"echo "picked $n"
# The script exits here. When the timer fires the run is dispatched# again, to whichever agent is free - which need not be this one - and# the script starts over from the top.spool sleep 5s
# `pick` does not draw a new number on that second pass. It replays the# recorded one, so $n is what it was before the sleep: new process, new# machine, five seconds or thirty days later, same value.m="$(spool step "add" -- expr "$n" + 1)"echo "$n + 1 = $m"
Run it as-is first:
spool run ./durable.sh run: dev:default:run-2qyEKiaS7pTtkkZipicked 74
- replaying from checkpoint (completed steps are cached, not re-run)picked 7474 + 1 = 75 dev:default:run-2qyEKiaS7pTtkkZi completedThe pause between the two passes is the process being gone:
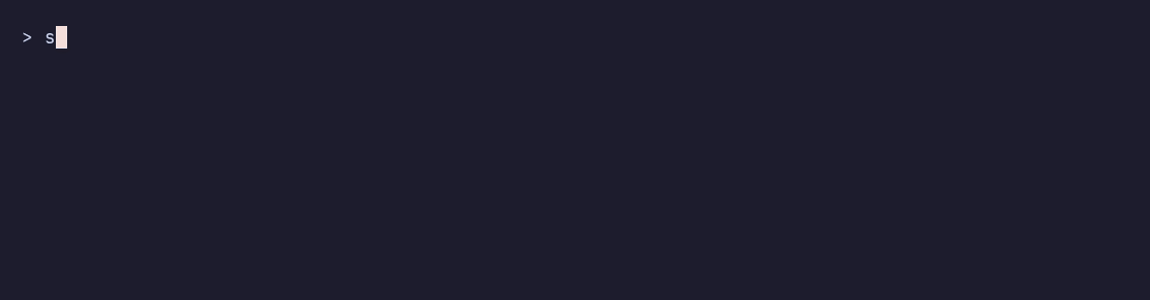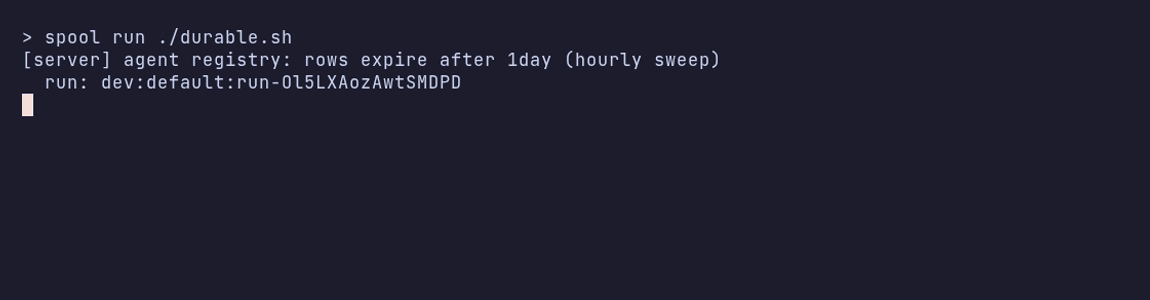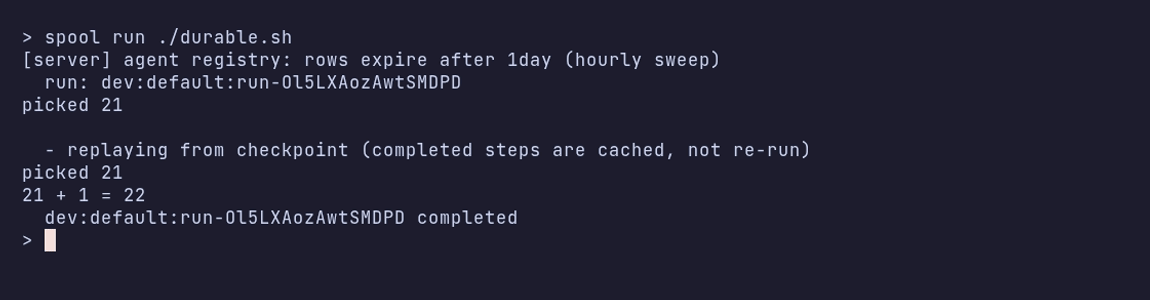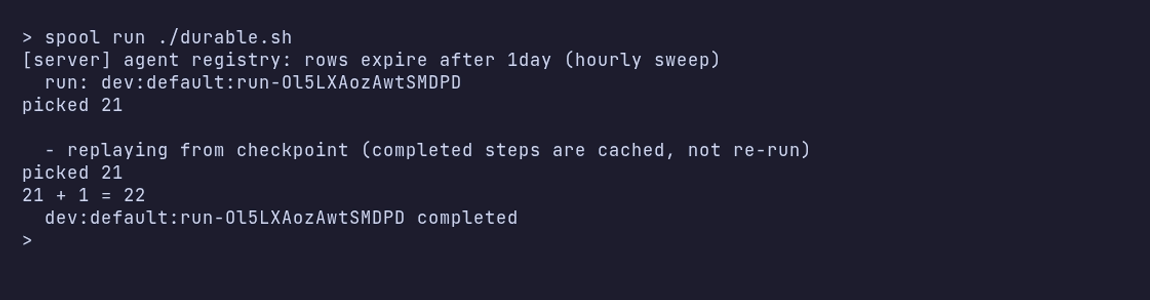
picked 74 appears twice because the script ran twice, and says 74
both times because pick replayed its checkpoint on the second pass.
Replay explains the model.
For the crash test, change the script’s spool sleep 5s to
spool sleep 60s so you have time to interrupt it. Then start a
persistent instance, pointed at a database file you name:
spool dev --db ./spool-demo.dbThis one process is the server, an agent, and the console at
http://localhost:18753. If the CLI points at another server, spool context use local switches to it (local and the
server). Leave it running and submit the script
from a second terminal:
spool submit ./durable.sh --followpick prints its number, then the run is asleep on spool sleep. Note
the number, then kill the instance hard:
kill -9 "$(pgrep -f 'spool dev')"The run’s state lives in ./spool-demo.db, not in the process you just
killed. Start the instance again against the same file:
spool dev --db ./spool-demo.dbOn startup it says resumed 1 in-flight run(s) from storage, and when
the timer fires the run finishes. spool logs <run-id> shows the last
pass:
picked 7474 + 1 = 75That is the number you noted before the kill: pick did not re-run, and
its checkpoint came out of ./spool-demo.db. Open
http://localhost:18753 to see the run’s page in the console. A deploy,
a reboot, or a thirty-day sleep that outlives the machine works the same
way as the kill -9.
The test, recorded:
On hyperspool.dev
Section titled “On hyperspool.dev”The same files run on the service at hyperspool.dev. Steps run on managed environments the service starts on demand, so you need no machine of your own.
1. Sign in at hyperspool.dev.
Sign-in is by invitation for now. If you don’t belong to an org yet, the console
offers to create one: a Free org that you own, with a project called
default. Later, + New organization in the org switcher does the
same.
2. Point the CLI at it. Create a personal access token under Settings > Tokens, then:
spool login https://api.hyperspool.devIt prompts for the token (or reads it from stdin, for scripts), picks
your org and project, saves a context for the server in
~/.config/spool/config.toml and makes it current. spool context get
shows which server, org and project commands use and why, and
spool context use local goes back to a running spool dev.
3. Submit.
spool submit pipeline.yaml --followSteps run in a managed container, or on a build VM on the Team and Business plans. Managed environments lists what each one has and what each plan includes, and when to run your own agent covers arm64, macOS, private networks and other toolchains.
Where to go next
Section titled “Where to go next”- Tour - thirty minutes through steps, timers, approvals, signals, events, and child workflows, all locally.
- Concepts - the vocabulary.
- The authoring model - the checkpoint/replay rules; read once before writing a real workflow.
- Workflows in your language - the same primitives in Python, TypeScript, Go, and Rust.
- Agents - the managed environments, and running your own agent when they don’t fit.
- Local and the server - how far
spool devtakes you, and what the service adds.