Run lifecycle
A run is one execution of a workflow. It has an id (<org>:<project>:run-<random>), a durable
event log, a status, and zero or more child runs. This page covers the states a run moves
through, how approvals and cancels end it, and what happens when an agent or the service fails
under it.
Status
Section titled “Status”| Status | Meaning |
|---|---|
running |
Still executing, or waiting for something. |
completed |
Finished successfully. |
failed |
A step or the workflow itself errored terminally. |
cancelled |
Stopped: by someone, by a rejected approval, by a cancel_on: event, by a concurrency policy, or because its parent stopped. |
unreadable |
Its history could not be opened, so nothing more can be shown. The console counts it as a failure. |
Every status but running is terminal. A terminal run never goes back to running.
A run’s page in the console opens on a headline saying what it is doing (“Waiting for approval”, “Asleep until 14:00”, “Failed at build”), a forecast of the time left based on earlier runs, and its steps as a journal, a waterfall against the clock, or a graph. See the run page.

Substate
Section titled “Substate”While a run is running, the service derives a finer substate from its event log, so the
console can say what the run is doing now. At most one is open at a time. The API returns the
substate and the console shows the words beside it.
| Substate | Console shows | The run is… |
|---|---|---|
queued |
queued | Not started yet, or started with nothing scheduled. |
executing |
running | Running one or more steps on agents. |
waiting_for_agent |
waiting for an agent | A step is scheduled and no agent has claimed it yet, but one could: the agents are busy, an environment is starting, your plan’s managed compute limit holds it for now, or an agent that could has stopped without saying so less than a day ago. |
unroutable |
no agent can run this | No agent can ever claim the step: nothing that advertises the capabilities it requires: is online in its project or was seen in the last day. Carries the missing capabilities. |
sleeping |
asleep | On a timer: spool sleep, a wait with a duration, or a paced fan-out. Carries the wake time. |
awaiting_signal |
waiting for approval, or waiting for <signal> |
Waiting for an approval, a spool wait signal, a wait on a signal, an event step or a wait_for_event: job. Carries name, approval (true for an approval), deadline_ms when the wait is bounded, and for an approval its prompt. |
awaiting_child |
waiting on another run | Waiting for a child workflow to finish. |
awaiting_call |
waiting on another run | Waiting for a run started with spool call. |
awaiting_lease |
waiting for a lock | Waiting for a concurrency lease (a job’s concurrency: group or spool lock) held by another run. Carries the group. |
Managed environments serve shell, polyglot, connector and build work, so unroutable
means one of these:
- a step asks for something else (a
gpu,arm64,macos) and no agent of yours covers it; - a
buildstep on a plan without build VMs; - a step pinned with
agent:to an agent that is gone.
Start an agent that advertises the capability (see Running your own agent) or
fix the step’s requires:. spool run why <run> says which, and names the plan limit when one
holds the step (what your plan includes).
Before a run starts
Section titled “Before a run starts”A pipeline or graph with a top-level concurrency: or throttle: is admitted before it starts.
A run held back waits as queued; the console says “Queued for deploy” with how many runs are
ahead of it, or “Held by the deploy rate limit”. A skip or drop policy, or a full queue,
refuses the submit instead, and no run is created. See
run admission.
Your plan also caps how many runs an organization has running at once; the numbers are in
what your plan includes. Every run with status
running counts, asleep and waiting ones included.
A run started while the organization is at its cap is queued, whatever started it: a submit, a
push, a schedule or an event. It is listed as queued, spool run why says which cap holds it,
and it starts when a slot frees. A start is refused only when the organization already has 1,000
runs waiting.
Runs that a run starts itself never wait, since the run may be waiting on them: what it spawns
or calls, and the handler runs of events it emits. Child workflows and spool call runs don’t
count toward the cap. A spawned run and a handler run do count while they run.
Approvals
Section titled “Approvals”An approval step (a pipeline approval: job or a graph approval step) waits for a person.
While it waits the run is awaiting_signal with approval: true, and shows on Today and on the
run page under Needs you.
- Approve from the run page, from Today, or with
spool approve <run> [<job>]. The job name can be left out when the run waits at only one gate.spool approveasks for each field in turn, showing its type, options and default;--field name=valuefills one in (converted to the field’s type) and--no-promptskips the questions. Inspool run follow, pressaon the waiting step for the same form. The answer becomes the step’s output, so a later step readsnodes.<gate>.output.<field>(orsteps.<job>.output.<field>in a pipeline). - Reject from the run page or Today, with an optional reason. Reject cancels the run, with
the reason
rejected at <job>: <reason>, cancels the child runs it was waiting on, and records{"decision": "reject", "reason": ...}as the gate’s answer. From a terminal:spool reject <run> [<job>] [--reason <text>]. The HTTP route isPOST /api/v1/orgs/<org>/projects/<project>/runs/<run>/approvals/<job>/rejectwith an optional{"reason": "..."}.
The approve route (POST …/approvals/<job>) takes the form’s field values, and refuses a
decision key unless the form declares a field of that name, so a reject can never be read as an
approval. An approval with a timeout: that nobody answers resolves instead of failing; see
timeouts on waits and approvals.
A missing required field is refused (approval field "ticket" is required) and the run keeps
waiting. A gate can’t be answered with spool run signal.
When a step fails
Section titled “When a step fails”A failure holds back only the steps that depend on the failed one. Everything else in the run
carries on, approvals, waits and child runs included, so a failed run can stay running until a
gate is answered, rejected or cancelled. Once nothing more can run, the run ends failed if any
step failed without continue_on_error:.
Two details follow from that. A gate whose timeout: expires lets the steps behind it go ahead,
as if it had been approved. A failure() step runs as soon as the failure happens, without
waiting for gates, timers or child runs beside it. Dependencies
has the same rules from the pipeline side.
Lifecycle events
Section titled “Lifecycle events”A run publishes an event on the project bus when it starts, when it stops to wait for something outside itself, and when it finishes, so a handler can react. The event catalog lists the types and what each carries.
run.awaiting carries substate, waits_on (person, event or signal), the signal
name, the gate’s prompt and fields, the workflow_name, and a deadline_ms where the wait
is bounded. run.wait_expired and run.wait_withdrawn carry the same without substate or
deadline_ms. The fields every lifecycle event has are listed in
lifecycle events.
Point a handler at run.failed for a failure notifier, at run.awaiting to tell an approver, at
run.wait_expired to hear that nobody answered, or at run.* for all of them. These types are
reserved, so spool event emit can’t forge them.
Some waits and some runs publish nothing. A timer doesn’t, since a run asleep wakes by itself,
and nor does a script’s spool wait signal.
Child runs, dry runs and runs a handler started don’t announce themselves to handlers; see runs that don’t announce.
Cancelling
Section titled “Cancelling”spool run cancel <run-id> --reason "superseded by a newer build"The console’s Cancel run… does the same. Cancel appends a terminal cancelled event to the
run’s log and removes the run’s pending and claimed steps from the queue, so a step whose agent
died can’t keep coming back.
What happens to the children
Section titled “What happens to the children”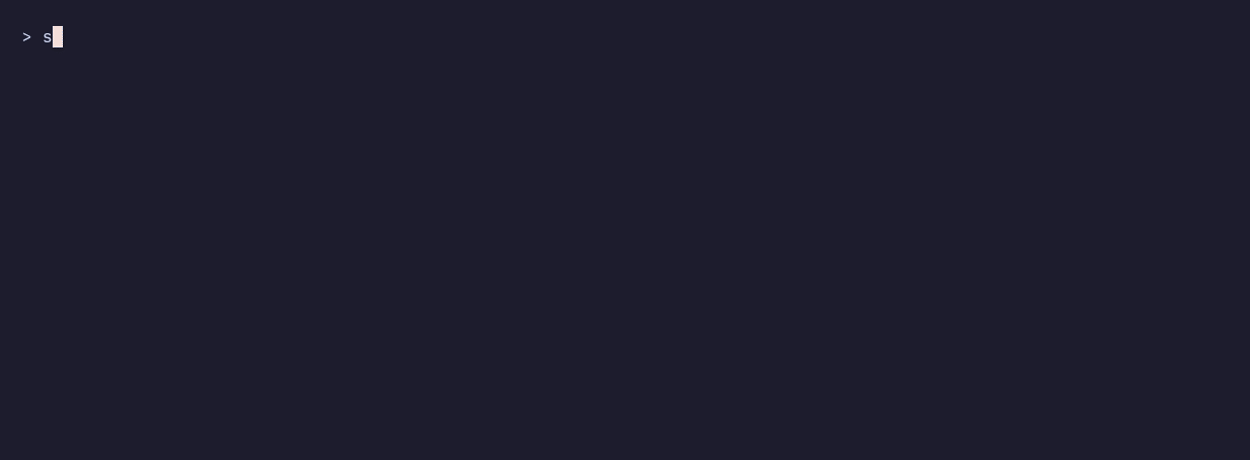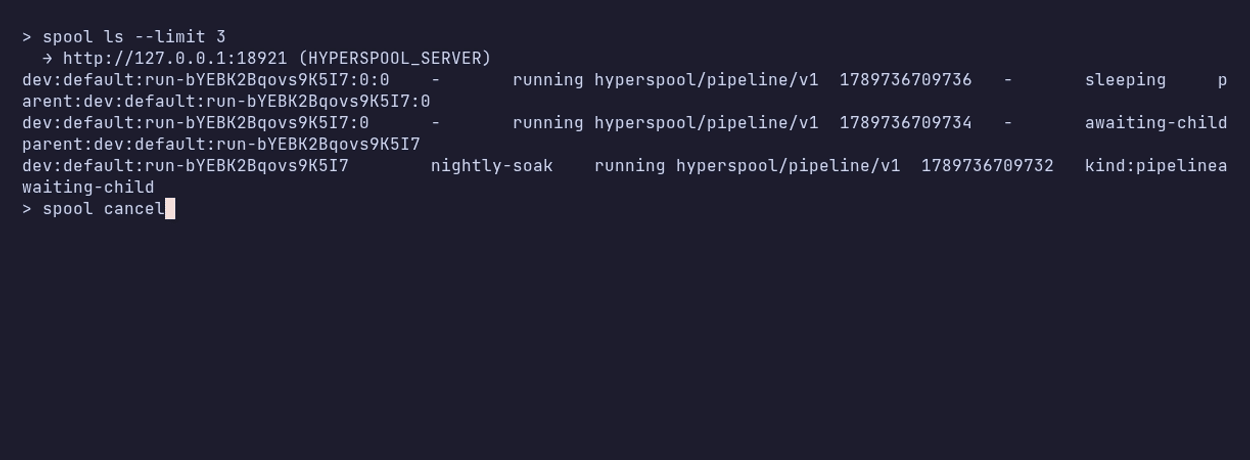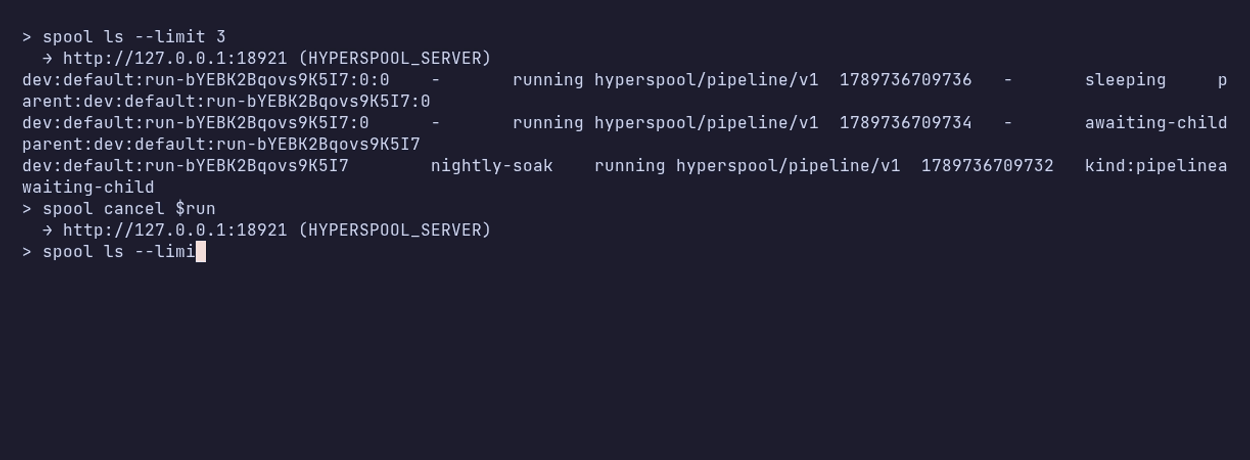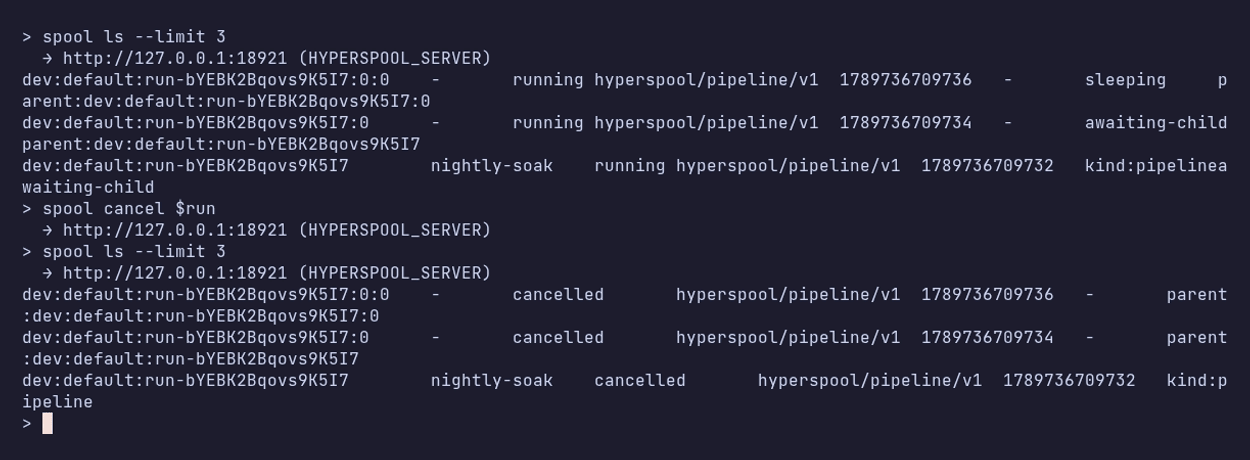
A run that reaches a terminal state cancels every child it was still waiting for: a workflow:
job, a workflow step, and spool call. That holds for any terminal outcome. Each cancelled
child does the same for its own children, so a cancel_on: event or one spool run cancel
reaches the whole tree. A child stopped this way records parent <run-id> is no longer running
as its reason, and its page says so.
A job failing on one branch doesn’t end the run while another still waits for a child: the run waits for that child as for any job beside a failure.
A cancelled script’s spool activity submit children are removed from the queue with it. They
never report, so spool run activities <run-id> keeps showing them as running.
spool spawn children are not cancelled: a spawned run outlives its spawner. Cancel one
directly if you want it stopped. Children that already finished are left alone.
Rerunning
Section titled “Rerunning”A finished run can run again as a new run:
- Rerun on the run page, or
spool run rerun <run-id>, submits it again with the same input and tags. - Rerun from here on a step, or
spool run rerun <run-id> --from <step>, starts at that step and reuses what the steps before it recorded. In a graph or pipeline those steps don’t run again. In a script the recorded calls return their results, but the code around them runs again from the top.--from site#2picks an iteration of a script site used in a loop.
A rerun of a dry run is dry too.
A rerun of a script run replays the script text that run recorded. If that script calls a
spool command by a name the CLI no longer has, spool run rerun or
spool workflow try --seed-from on it fails at the first such call. Submit the updated script as
a new run instead.
Dry runs
Section titled “Dry runs”Try it on the canvas starts a dry run of a graph: effects are stubbed, waits finish at once and approvals answer themselves. A dry run is admitted at once (no concurrency or throttle), publishes no lifecycle events, gets no forecast, is listed apart from normal runs, and is deleted a day after it ends. See Try it.
When an agent dies
Section titled “When an agent dies”A step in flight holds a 30-second lease. If the agent stops renewing it (crash, network
partition, kill), the lease expires. The agent then has 15 more seconds to get back in touch and
carry on with the step; after that the step goes back to the queue and another capable agent
claims it. The step runs again from the start. Completed spool step boundaries return their
recorded output on replay, so the rerun skips work already done.
When the service restarts
Section titled “When the service restarts”The event log is durable. After a restart every run that had not finished continues from its recorded history. A run that was asleep or waiting for a signal is still asleep or waiting. Finished runs stay finished.
Retries and timeouts
Section titled “Retries and timeouts”Infrastructure failure recovers by itself, as the two sections above describe: completed
spool step / stepFn boundaries return their recorded results and only the unfinished tail
runs again. There is nothing to configure and nothing to turn off.
A step that fails is your result, and it isn’t retried unless you say so:
- A
steps:orscript:job, and a graph step that runs on an agent, takeretry::attempts(total, including the first),backoff(delay before attempt 2, doubling after),max_backoff(a ceiling on that delay) andexit_codes(retry only these). Seeretry:. A step out of attempts fails the run. - Fan-out activities take
--attempts,--backoffand--retry-on-exitonspool activity run/spool activity submit. A fan-out child out of attempts does not fail the run by itself:spool activity waitreturns its last output and exit code, and the script decides.
A determinism violation fails loudly and is not retried, because replaying it would fail the same way.
A timeout: caps how long one step may run. An agent caps any step at one hour by default, and
a job’s or node’s timeout: overrides that, up to 24 hours on an agent of your own. A managed
environment holds a step for less; see its
limits. The in-process agent behind spool run and
spool dev applies no default.
On expiry the agent kills the step’s process group and the step fails, which then feeds retry:
if set.
Timeouts on waits and approvals
Section titled “Timeouts on waits and approvals”Two different things are spelled timeout:, and they end opposite ways. The one above bounds a
step and fails it. The one on a wait:, approval: or wait_for_event: job (or a graph wait,
approval or event step) bounds a wait and resolves it: the step succeeds, and the run
carries on.
So an approval nobody answers does not fail the run. The gate expires, the job completes, and whatever depended on it runs as though the answer had been yes:
gate: approval: { prompt: "Ship it?", timeout: 5s }deploy: depends_on: [gate] # runs when the gate expires, unapproved steps: - { name: ship, run: ./deploy.sh }A bounded wait says which way it resolved, so branch on that when it matters:
deploy: depends_on: [gate] if: ${{ !steps.gate.output.timed_out }}timed_out is set only on a job that declares a timeout:, and reading it on one that doesn’t
is refused at submit. See approval jobs. An expiry also
publishes run.wait_expired, so a handler can say what went ahead without a decision; only the
if: changes what runs.
Log size
Section titled “Log size”Each run can store a limited amount of log output, set by your plan; the numbers are in what your plan includes. That is far more than a normal CI log.
Once a run passes it, a line in the log says so and the rest of that run’s output is not stored. The job itself keeps running and finishes as it would have, with its exit code and outputs intact.
If a step prints far more than you need to read, send the bulk to a file and keep it as an artifact instead.
Retention
Section titled “Retention”A finished run is deleted, with its history, logs and annotations, once it is older than your plan’s retention (what your plan includes). Age counts from when the run finished. A running run is never deleted, however old.
Other records have fixed lifetimes: bus events are kept 30 days, webhook deliveries 7 days, and dry runs a day.